

About the project.
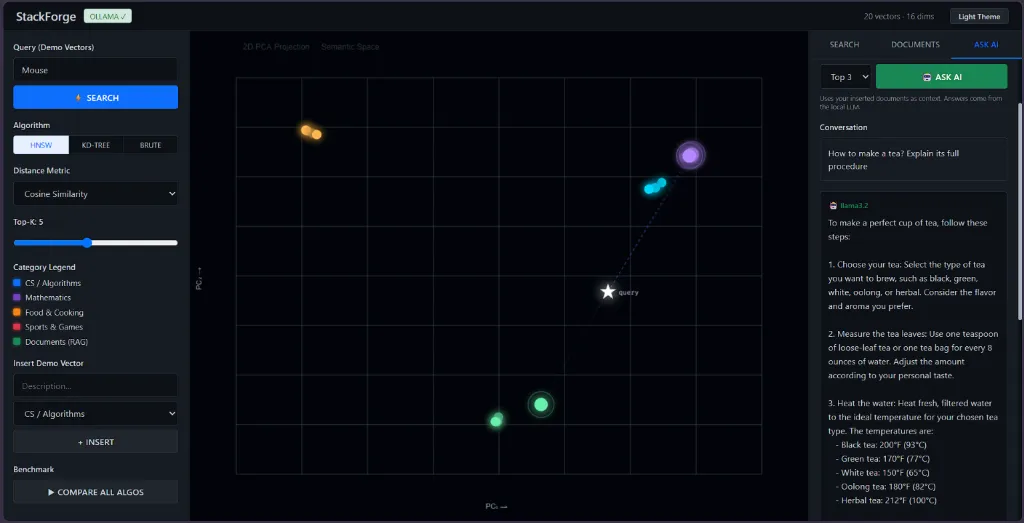
A zero-dependency vector database built from scratch in Java 17+ featuring side-by-side HNSW graph search, KD-Tree indexing, and Brute-Force search across Cosine, Euclidean, and Manhattan metrics. Integrated with a local RAG pipeline via Ollama (nomic-embed-text and llama3.2) for document ingestion, top-k context retrieval, and document-grounded answers. Includes a REST API for vector operations and search benchmarking alongside an interactive Web UI with live PCA vector projections.
Features
>HNSW, KD-Tree, and Brute-Force algorithms with Cosine, Euclidean, and Manhattan metrics.
Ollama integration with nomic-embed-text and llama3.2 for top-k context retrieval and document-grounded answers.
Interactive 2D vector visualization with live search benchmarking across graph and tree index structures.
Structured REST API endpoints delivering efficient CRUD operations, error handling, and validated data contracts.
Optimized database queries, clean architectural design, and minimal latency for production workloads.
Features
>Tech Stack
/> Java
Object-oriented programming language for building robust, scalable enterprise backend applications.
 Ollama
Framework for running and embedding open-source large language models locally.
 RAG
Retrieval-Augmented Generation architecture combining vector search context with LLM inference.
 Vector Databases
Specialized database engines engineered to store, index, and query high-dimensional vector embeddings.
 Vector Embeddings
High-dimensional numerical representations capturing semantic meaning of text and data.
 REST APIs
Architectural style for designing structured, scalable networked endpoints using standard HTTP.
 Maven
Build automation and dependency management tool primarily used for Java projects.
 Git
Distributed version control system for tracking changes and collaborating on codebases.
 GitHub
Cloud-based hosting service for Git repositories with CI/CD workflows and collaboration.